Import Parquet to Sqlite Automatically
Looking to import data from Parquet to Sqlite?
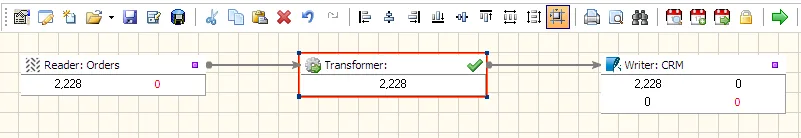
Advanced ETL Processor Enterprise provides everything you need to automate the data import without writing custom scripts. Visually map and transform your fields, then run the Import immediately or schedule it to repeat automatically.
Parquet is a columnar storage file format widely used in modern analytics platforms. It was designed to efficiently store and process large datasets, which makes it ideal for data pipelines and data lakes.
- High compression - reduces storage requirements significantly
- Column based format - improves query performance for analytics
- Efficient processing - reads only the required columns
- Widely supported - used by Spark, Hadoop, Python, and many analytics tools
- Great for large datasets - optimized for big data workloads
However, Parquet files are not always convenient for applications that need a simple embedded database. That is where SQLite becomes extremely useful.
Video: Watch the Data Import in Action
Watch a general data-import walkthrough showing how to connect databases, map fields, and run an import in Advanced ETL Processor.
Useful links for this import
Start with the Advanced ETL Processor Enterprise overview, then download the fully functional 30-day trial. The import-data hub lists the other Parquet import workflows.
FAQ
Can Advanced ETL Processor import Parquet to Sqlite?
Yes. Advanced ETL Processor can read Parquet, map fields, validate data, write to Sqlite, and log the import.
Do I need to write scripts for the import?
No scripting is required for the normal import workflow. You can configure the reader, writer, mapping, validation, and schedule visually.
Can the Parquet import run on a schedule?
Yes. The package can run on a schedule, process matching Parquet files, archive originals, and write rows to Sqlite with the same validation rules each time.
Can imported data be transformed before loading?
Yes. You can clean values, convert data types, calculate fields, split columns, and apply lookup rules before writing to the target.
Can bad rows be logged or rejected?
Yes. Add validation rules so rejected rows, failed files, row counts, and error details are visible after each run.
What should I check before the first production import?
Check source layout, target table, key fields, data types, date formats, write mode, archive folder, and failure handling.
When should I not automate the import yet?
Do not automate it until the source layout, target table, key fields, and bad-row handling are clear. Automation repeats rules; it does not invent them.
Can I test the import before buying?
Yes. Download the fully functional 30-day trial, build one small import, and test it with a deliberately awkward sample file.
Automate Your Parquet-to-Sqlite Imports
Download the fully functional 30-day trial and build your first import using your own Parquet and Sqlite databases.
Direct download. No registration required.