Import Parquet to ODBC Automatically
Import Parquet to ODBC automatically and simplify the process of loading modern analytics datasets into virtually any database system. Parquet files are widely used in data platforms because they are highly efficient for storing large volumes of data. However, many enterprise systems still rely on databases accessed through ODBC drivers. With Advanced ETL Processor, you can automatically import Parquet files into any ODBC compatible database without writing scripts or custom code.
Why Parquet Is Popular For Data Pipelines
Parquet is a modern column oriented storage format designed for analytics and big data processing. Many organizations use Parquet files to store large datasets because the format provides high performance and efficient storage.
- Column based storage improves analytical query performance
- Efficient compression reduces file size and storage costs
- Fast data scanning reads only required columns
- Optimized for large datasets used in data lakes and analytics platforms
- Supported by many technologies including Spark, Python, and cloud analytics systems
Because of these benefits, many data platforms export reports and datasets in Parquet format. However, operational systems often rely on relational databases accessed through ODBC connections.
Why ODBC Connectivity Is Important
ODBC, or Open Database Connectivity, is a standard interface used to connect applications to databases. It allows software to communicate with many different database systems through a common driver based interface.
- Universal database connectivity
- Compatible with many database systems
- Widely supported by enterprise software
- Flexible integration with legacy and modern databases
- Standard method for database communication
Because ODBC supports a wide variety of databases, importing Parquet files through an ODBC connection allows organizations to integrate modern analytics data into many different systems.
Automate Parquet To ODBC With Advanced ETL Processor
Instead of writing custom integration scripts, you can automate the entire workflow using Advanced ETL Processor. The platform provides a visual ETL designer that allows you to configure automated data pipelines quickly and reliably.
Benefits of Using Advanced ETL Processor
- No scripting required - everything is handled by the ETL engine
- Native support for reading Parquet files
- Direct integration with any ODBC compatible database
- Visual drag and drop ETL workflow designer
- Automated scheduling of data imports
- Perform transformations, filtering, and validation
- Reliable automation for production data pipelines
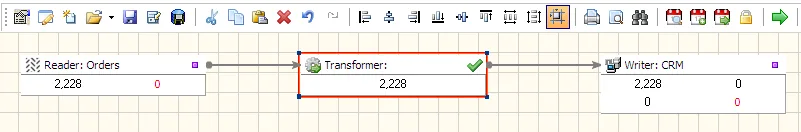
Everything is done by Advanced ETL Processor automatically. You simply configure the Parquet source, connect to the ODBC destination database, map the fields, and run the ETL job. The platform handles the extraction, transformation, and loading process without scripting.
Typical Parquet To ODBC Workflow
- Connect to the Parquet file source
- Select the destination database using an ODBC driver
- Map Parquet fields to the destination table
- Run the ETL job or schedule automated processing
Once configured, the ETL workflow can automatically process new Parquet files and load the data into any ODBC compatible database.
Where this import fits
Import Parquet to ODBC Automatically is useful when Parquet data needs to feed ODBC, reporting databases, operational systems, migration jobs, or downstream ETL workflows. Use it when the same import needs validation, mapping, transformations, scheduling, and logs instead of another manual load.
Do not automate the import until the source layout, target table, key fields, write mode, and failure behaviour are agreed. Automation repeats rules; it does not rescue unclear ones.
Useful links for this import
Start with the Advanced ETL Processor Enterprise overview, then download the fully functional 30-day trial. The import-data hub lists the other Parquet import workflows.
Business usage examples
Many companies export analytics datasets in Parquet format. Automated ETL pipelines can im
Import Parquet data into ODBC with a repeatable, logged workflow instead of a manual load.
Some legacy applications rely on databases accessible through ODBC drivers. Converting Par
Import Parquet data into ODBC with a repeatable, logged workflow instead of a manual load.
Organizations frequently generate Parquet reports from analytics systems. ETL workflows ca
Import Parquet data into ODBC with a repeatable, logged workflow instead of a manual load.
Watch Advanced ETL Processor In Action
FAQ
Can Advanced ETL Processor import Parquet to ODBC?
Yes. Advanced ETL Processor can read Parquet, map fields, validate data, write to ODBC, and log the import.
Do I need to write scripts for the import?
No scripting is required for the normal import workflow. You can configure the reader, writer, mapping, validation, and schedule visually.
Can the Parquet import run on a schedule?
Yes. The package can run on a schedule, process matching Parquet files, archive originals, and write rows to ODBC with the same validation rules each time.
Can imported data be transformed before loading?
Yes. You can clean values, convert data types, calculate fields, split columns, and apply lookup rules before writing to the target.
Can bad rows be logged or rejected?
Yes. Add validation rules so rejected rows, failed files, row counts, and error details are visible after each run.
What should I check before the first production import?
Check source layout, target table, key fields, data types, date formats, write mode, archive folder, and failure handling.
When should I not automate the import yet?
Do not automate it until the source layout, target table, key fields, and bad-row handling are clear. Automation repeats rules; it does not invent them.
Can I test the import before buying?
Yes. Download the fully functional 30-day trial, build one small import, and test it with a deliberately awkward sample file.
Stop struggling with fragile ETL scripts. Start shipping reliable workflows.
Download the fully functional 30-day trial. Build your first automation in 10 minutes or less.
Direct link, no registration required.